Data connectors for every source in your stack
Start with ready-made connectors for the systems you run on. When a source isn't covered, point Maia at its API documentation and it builds the connector for you, with authentication, pagination, and test requests included.











Every source has a way in
Ready-made where it exists. Built where it doesn't.
Pre-built connectors for the sources teams use most. Pick the data source, choose a full or incremental load, and run. Basic mode builds the query for you; Advanced mode lets you write it.
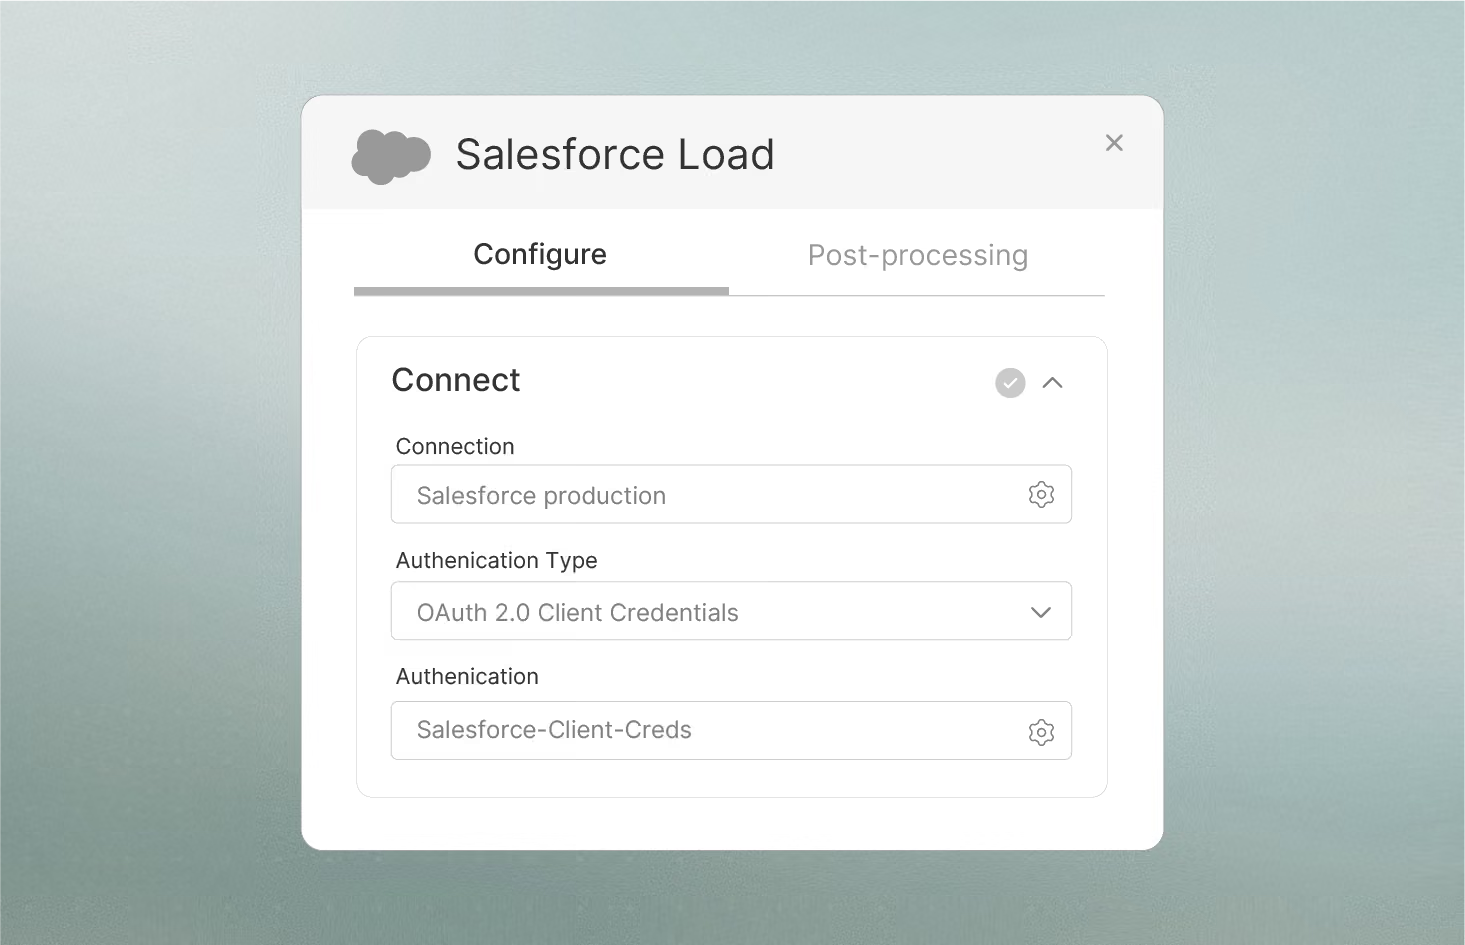
Templates for popular REST APIs, with endpoints, authentication, and parameters already set up. Open one, add or remove endpoints, and save it as your own connector. Need a template we don't have yet? Request one.
Request a Flex connector
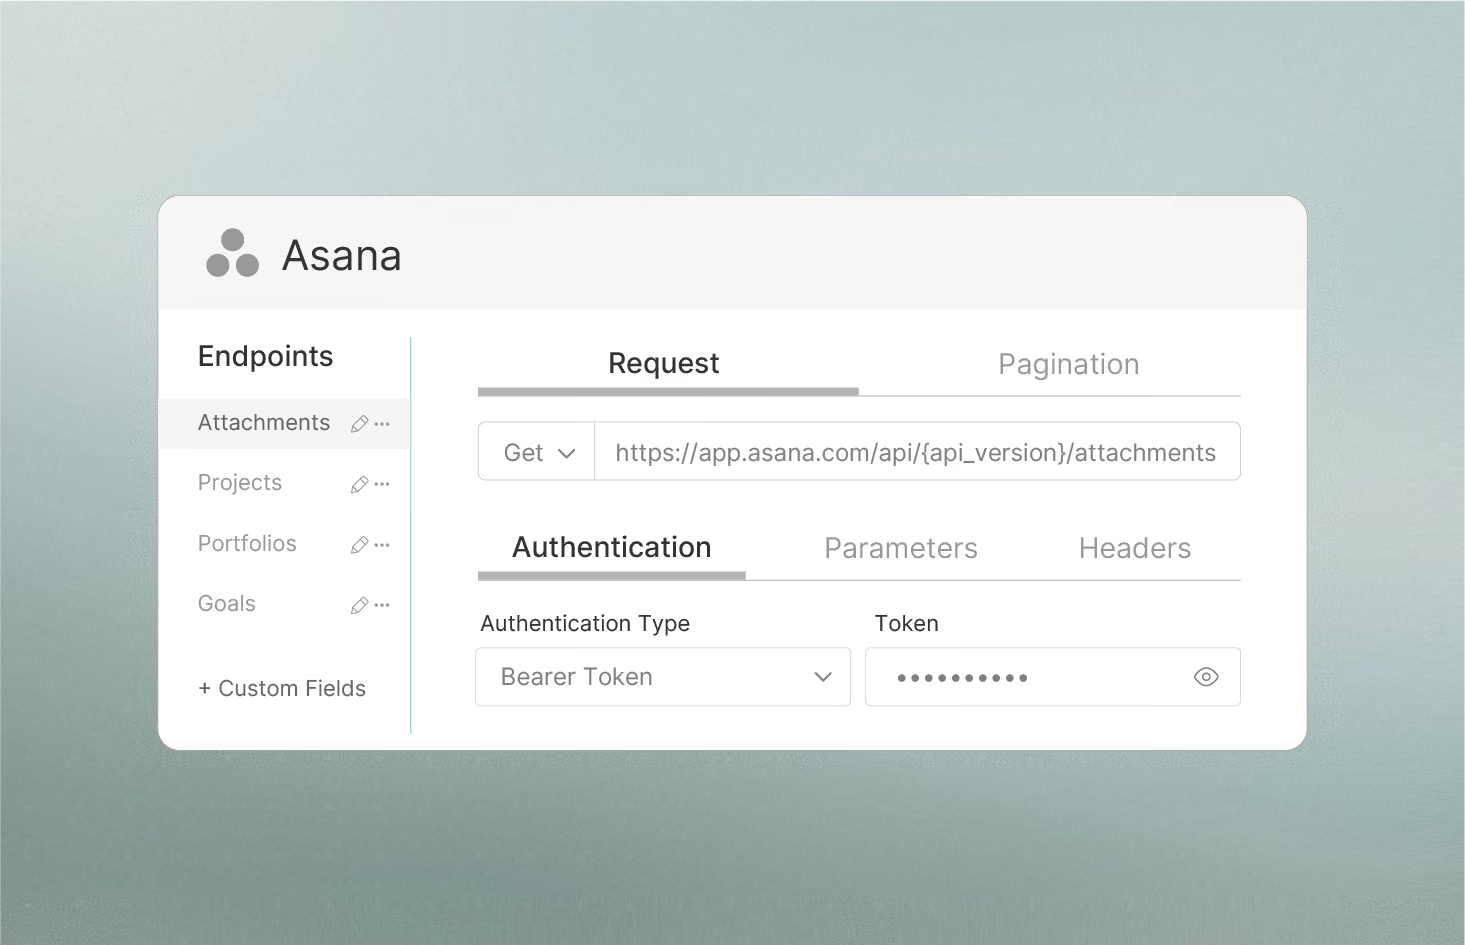
Connect to any REST API that returns JSON. Add the endpoints, set authentication and pagination, test the response, and save. No code required.
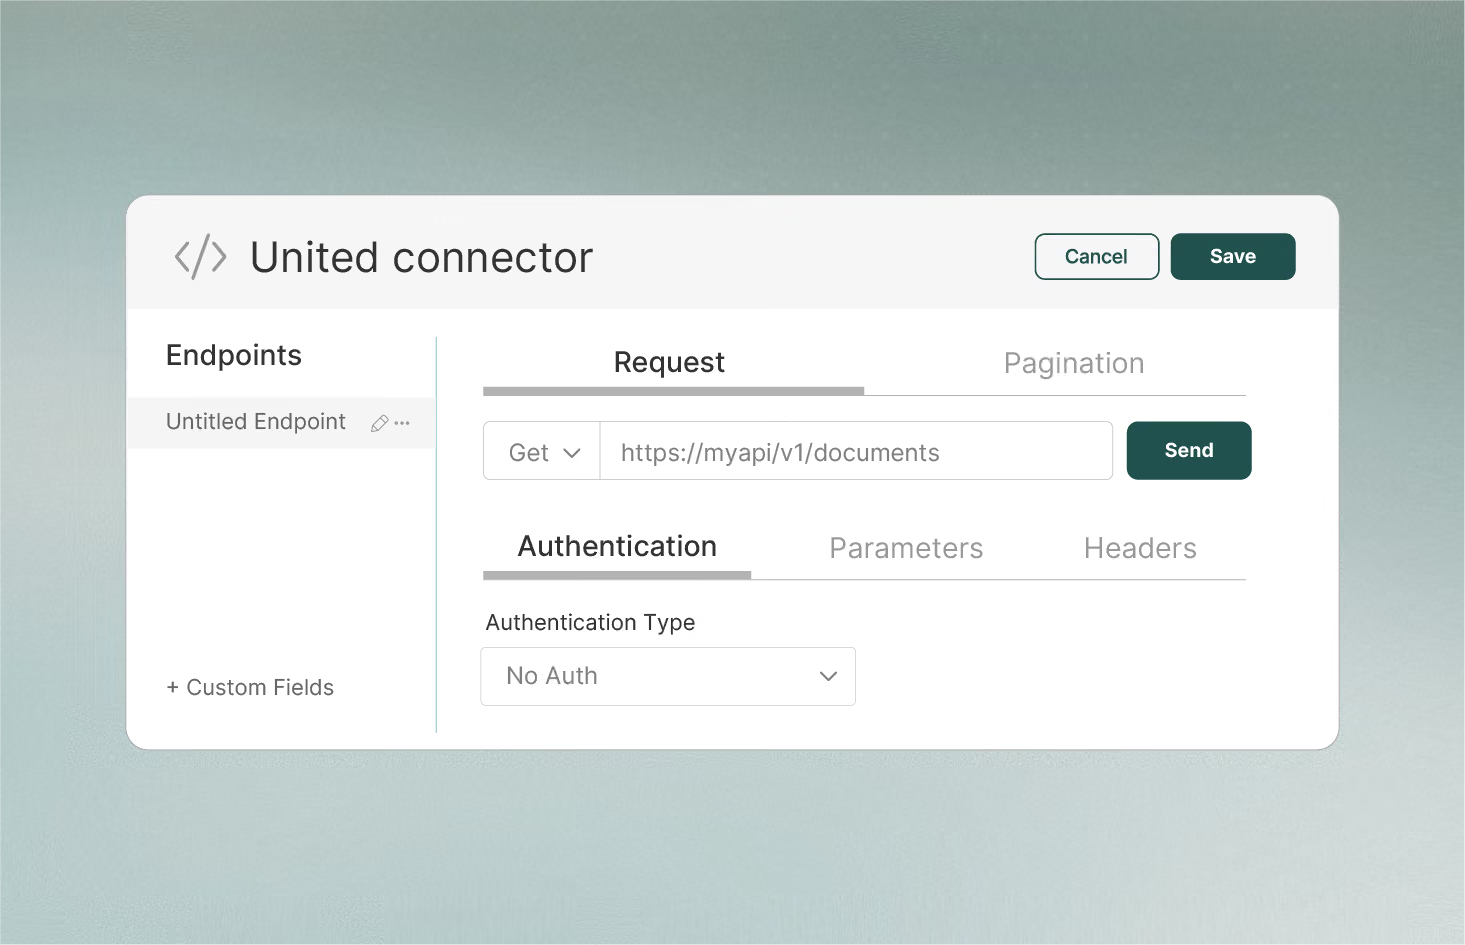
Paste a link to the API's documentation, or upload the spec as a PDF, YAML, or JSON file. Maia finds the endpoints, works out the authentication, sets up pagination, and runs test requests. Then it hands the connector back for you to review and save.


Proven in production
A connector is step one. Maia builds the rest.
Describe what you need. Unlike most data connection tools, Maia doesn't stop at the connector: it builds the pipeline around it, covering load, transform, and schedule, and runs it on your cloud data platform.

Load as a step
Connectors run inside orchestration pipelines, alongside the rest of your work.

Transform in your warehouse
Shape data with low-code components, SQL, or Python, executed on your cloud data platform.

Run it from anywhere
Maia samples up to 200 rows before configuring a component, only with your permission.
Batch and real-time, from one platform
Move data on the schedule your pipelines need, in whichever mode fits the source.
Reload the complete dataset on every run.
Each run only picks up what's changed since the last load.
Schedule loads as steps in an orchestration pipeline, alongside the rest of your work.
Oracle, Microsoft SQL Server, MySQL, PostgreSQL, Db2 for IBM i
Reads the database's change log rather than querying tables.
The streaming runner is deployed in your infrastructure, so change data never leaves it.
Picks up new columns and data type changes from the source.
Snapshot historical data in batches between streaming, so pipelines stay live.
Secure connections to sources, wherever they live


Authentication
Connect with OAuth, API keys, bearer tokens, or basic auth. Credentials are stored as secrets, not in a connector's configuration.

Private and restricted networks
Run Maia's runners in your own cloud with hybrid deployment, connect over AWS PrivateLink, and allowlist Maia's IP ranges where your sources require it.


Got a source we don’t cover yet?
Point Maia at the docs and watch it build the connector.
Join Matillion
We need driven, curious people who think big and move fast to join our team.