- Blog
- 09.16.2024
- Data Fundamentals, Product, Leveraging AI
Sentiment Analysis in Databricks with OpenAI GPT-4o

This article explores the practical application of Sentiment Analysis within Databricks using OpenAI GPT-4o. It presents a comprehensive guide on various techniques for executing Sentiment Analysis, with a focus on implementation through Python.
The discussion will include an overview of the advanced capabilities of OpenAI GPT-4o and will commence with a foundational explanation of what Sentiment Analysis entails.
What is Sentiment Analysis?
Sentiment Analysis is an application of natural language processing (NLP) and machine learning. It focuses on determining the sentiment or emotional tone behind textual data. This technique aims to classify text as positive, negative, or neutral, employing algorithms that analyze patterns in language, syntax, and context. For data engineers and data architects, implementing sentiment analysis can involve designing pipelines that efficiently preprocess large text datasets.
Possible applications include:
- Customer Feedback Analysis: Automatically categorize customer reviews for products or services to identify prevalent sentiments, enabling companies to quickly address issues or promote favorable aspects.
- Social Media Monitoring: Continuously analyze tweets or posts to gauge public sentiment about events, brands, or trending topics, supporting real-time decision-making and PR strategies.
- Financial Market Predictions: Analyze news articles, financial reports, and social media mentions to gauge the sentiment around stock performance, helping in automated trading and investment strategies.
What is OpenAI GPT-4o?
OpenAI GPT-4o is a variant of the GPT-4 model optimized for more efficient resource utilization and accelerated performance in database query generation and anomaly detection tasks. It leverages advanced unsupervised learning techniques to enhance natural language understanding, making it highly adept at automating SQL query formulation and optimizing complex data processing pipelines. With integrated support for distributed data architectures, GPT-4o can seamlessly scale across cloud environments, ensuring robust, low-latency processing. This model’s ability to contextualize data relationships and generate actionable insights with minimal latency makes it a potent tool for modern data-driven infrastructures.
GPT-4o offers significant advantages, including advanced natural language understanding, context-aware responses, and the ability to generate human-like text, which make it an exceptional tool for applications like customer support, content creation, and complex querying in cloud databases. Its advanced contextual analysis and versatility streamline workflows, saving time and resources. However, these benefits come with certain drawbacks, such as the need for substantial computational resources, potential biases in generated content, and concerns regarding data privacy. To optimize its utility, GPT-4o is best employed in situations where high-quality, coherent, and contextually relevant text generation is essential, and where there are safeguards or oversight to mitigate risks associated with biases and data security.
How to perform Sentiment Analysis in Databricks with OpenAI GPT-4o using Python
Start by installing the prerequisite libraries (note the Databricks SDK for Python is in beta, version 0.28.0, at the time of writing):
python3 -m pip install databricks-sdk openai
Then load your source data into Databricks. The example below involves product reviews, and the data has already been loaded into a managed table named "stg_sample_reviews" with four columns: id (the primary key), stars, product and review.
Here is the Python script. Note it is good practice to handle your host and token credentials more securely than shown in this simple example. You might choose to use environment variables or a secret management service instead of hardcoding them.
Set the following values to those in your own Databricks workspace:
- sqlWhId - The ID of your SQL Warehouse
- vCatalog - Your Unity Catalog name
- vSchema - Your Unity Catalog Schema name (a.k.a. Database name)
To authenticate with OpenAI you will need to set up an environment variable named OPENAI_API_KEY containing your API key.
from databricks.sdk import WorkspaceClient
from databricks.sdk.service.sql import StatementParameterListItem

from openai import OpenAI

sqlWhId = "xxxxxxxxxxxxxxxx"
vCatalog = "your-catalog-name"
vSchema = "your-schema"

modelname = "gpt-4o"
tablename = "gpt_4o"

systemPrompt = "Your job is to analyze online product reviews"

# Function that will be called for every input row
def process_row(resp):
    userPrompt = f"""Provide a numeric rating that reflects the overall sentiment of the review.
The rating should be a single number between 1 and 5, where 1 represents the most negative sentiment and 5 represents the most positive sentiment.
Respond with the numeric rating only. Do not include any justification of the rating.
review: {resp}"""

    ccresp = oaisdk.chat.completions.create(
                   model=modelname,
                   temperature=1,
                   messages=[ {"role": "system", "content": systemPrompt},
                              {"role": "user",   "content": userPrompt} ])

    msg = ccresp.choices[0].message.content.strip()
    return(msg)

# Establish an OpenAI connection using environment variable OPENAI_API_KEY
oaisdk = OpenAI()

# Connect to workspace
wsclient = WorkspaceClient(
  host  = 'https://xxxxxxxxx.cloud.databricks.com',
  token = 'dapixxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx'
)

ddl = wsclient.statement_execution.execute_statement(warehouse_id=sqlWhId,
                                  catalog=vCatalog,
                                  schema=vSchema,
                                  statement=f"CREATE OR REPLACE TABLE `stg_sample_reviews_{tablename}` (`id` INT NOT NULL, `ai_score` VARCHAR(1024) NOT NULL)")

print(ddl.status)

# Fetch rows from the table
xsr = wsclient.statement_execution.execute_statement(warehouse_id=sqlWhId,
                                  catalog=vCatalog,
                                  schema=vSchema,
                                  statement="SELECT `id`, `review` FROM `stg_sample_reviews`")

print(xsr.status)

for r in xsr.result.data_array:
    ai_score = process_row(r[1])
    print(f"ID {r[0]}: Score: {ai_score}")
    dml = wsclient.statement_execution.execute_statement(warehouse_id=sqlWhId,
                                  catalog=vCatalog,
                                  schema=vSchema,
                                  statement=f"INSERT INTO `stg_sample_reviews_{tablename}` (`id`, `ai_score`) VALUES (:id, :ai_score)",
                                  parameters=[ StatementParameterListItem.from_dict({"name": "id", "type":"INT", "value": r[0]}),
                                               StatementParameterListItem.from_dict({"name": "ai_score", "type":"INT", "value": ai_score}) ])
After running the above script, you should find a new table has been created, which contains the AI-generated review score for every input record. Join this table to the original on the common "id" column to compare the AI-generated sentiment scores against the original star review.
The LLM was asked to score between 1 and 5, so you may choose to classify the scores more broadly as follows:
- 4 or 5 - Positive
- 3 - Neutral
- 1 or 2 - Negative
Sentiment Analysis in Databricks using Matillion
In the Matillion Data Productivity Cloud, orchestration pipelines like the one shown in the screenshot below can:
- Directly extract and load data, or call other pipelines to do so (as shown)
- Invoke OpenAI GPT-4o, with a nominated prompt, against all rows from a nominated table
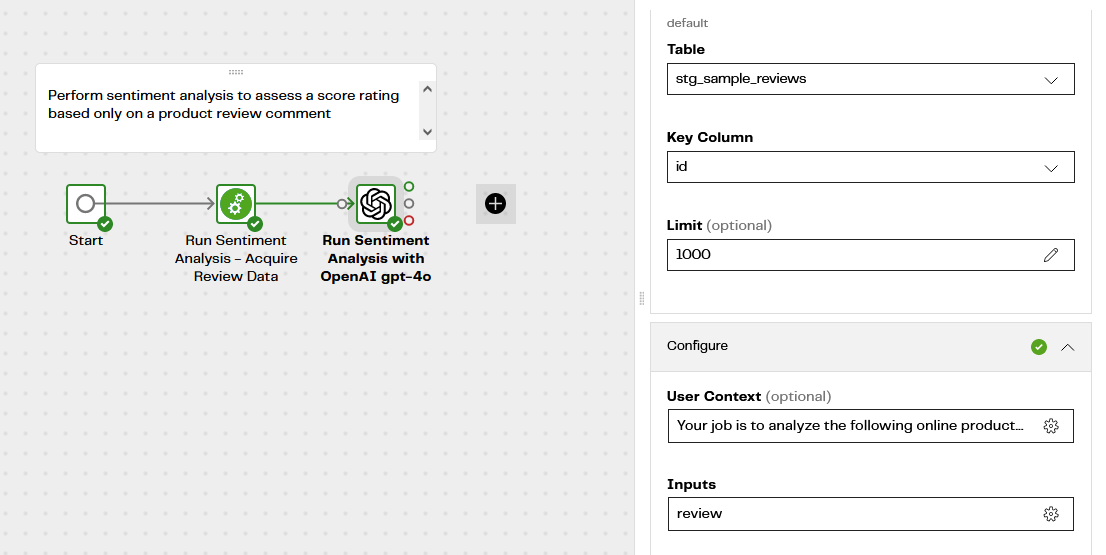
Performing Sentiment Analysis in Databricks using Matillion
Data pipelines such as this manage all the connectivity and plumbing between the Databricks source and target tables, and the LLM.
This allows you to focus on the overall design and architecture, and the data analysis. To compare the AI-generated sentiment scores against the original star review, use a transformation pipeline like the one in the next screenshot.
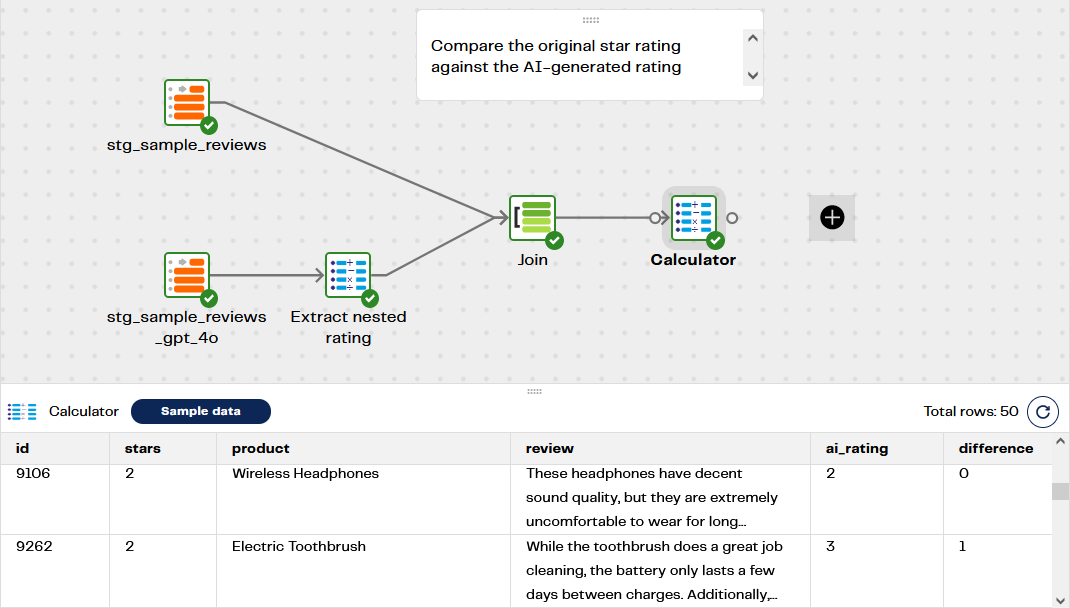
Checking the results of Sentiment Analysis in Databricks using Matillion
The data sample shows two of the records. In one case the LLM's decision matches the original sentiment identically, but in the other record the ratings differ slightly. This is an example of the subjective nature of sentiment analysis.
Summary
Matillion is a versatile data pipeline platform designed for accelerated AI and analytics at scale. It enhances productivity and collaboration by offering a code-optional interface, facilitating rapid pipeline development. Matillion integrates seamlessly with hyperscalers, CDPs, LLMs, and vector stores, supporting a wide range of data sources. The platform includes pre-built, no-code components and extensive connectivity options, also allowing you to easily build your own custom connectors via REST APIs. Hybrid SaaS deployment, comprehensive data lineage, and reverse ETL capabilities enrich its robust functionality. Advanced features include Git integration and AI-generated documentation to streamline workflows, while AI components augment data engineering tasks.
For more examples of Matillion's AI components in action, check out our library of AI Videos and Demos.
To try Matillion yourself, using your own data, sign up for a free trial.
If you are already a Matillion user or trial customer, you can download the sentiment analysis example shown in the screenshots earlier, and run it on your own platform.
Ian Funnell
Data Alchemist
Ian Funnell, Data Alchemist at Matillion, curates The Data Geek weekly newsletter and manages the Matillion Exchange.
Follow Ian on LinkedIn: https://www.linkedin.com/in/ianfunnell
Featured Resources
Why 2026 Changes Everything for Enterprise Data and AI
This year marks a turning point. Enterprises are moving from AI experimentation to practical deployment – get the exec ...
BlogThe Future of Data Belongs to the Bold: Why Being a Challenger Matters When Choosing a Data and AI Partner
Matillion has been named a Challenger in the 2025 Gartner® Magic Quadrant™ for Data Integration Tools – recognition that we ...
Data SheetsReady to lead your team into an AI-first future?
95% of generative AI pilots at companies are failing, according to ...
Share: